TOBIAS HINZ
Research Scientist
Meta Superintelligence Labs
I am a Research Scientist at Meta Superintelligence Labs, where I work on generative media models for multimodal data focusing on image, audio, and video generation. Previously I was the tech lead for core foundational models at Adobe Firefly, responsible for developing the next generation of Generative AI models, and a Research Engineer at Adobe Research where I started the engineering efforts of Adobe Firefly.
I obtained my PhD at the Knowledge Technology group at the University of Hamburg (Germany). Before that, I completed a research oriented Master's degree in Intelligent Adaptive Systems at the University of Hamburg. I received a Bachelor's degree in Business Informatics at the University of Mannheim, during which I also studied at the National University of Singapore for one semester.
News
- 07/2026: Meta Superintelligence Labs shared an early preview of Muse Video, our text/image-to-audio-video model.
- 02/2026: We shipped an updated lip-syncing model with better quality, higher resolution, and faster sampling.
- 02/2026: Our PRIS paper on prompt design for inference-time scaling in text-to-visual generation got accepted to CVPR 2026.
- 11/2025: Check out the first model release I contributed to at Meta: lip-syncing.
- 06/2025: I started a new role as Research Scientist at Meta GenAI Research in Menlo Park.
- 03/2025: Our ShotAdapter paper on text-to-multi-shot video generation with diffusion models got accepted to CVPR 2025.
- 10/2024: I attended Adobe MAX where Adobe announced the public beta of our text-to-video model as well as GenExtend (powered by our video model) integrated in Premiere Pro.
- 09/2024: A first sneak peek of our foundational text-to-video model at Adobe Firefly that we've been working on for the past year.
- 06/2024: I attended CVPR 2024 in Seattle. Lots of great papers and conversations.
- 03/2024: Our papers on Personalized T2I and Efficient Video Diffusion got accepted to CVPR 2024.
- 11/2023: I have started leading the efforts on developing foundational text-to-video models for Adobe Firefly.
- 10/2023: Our second generation of Firefly models was announced today at the Adobe MAX conference.
Features I Worked On


Selected Publications
For a full list, have a look at my Google Scholar page.
Rethinking Prompt Design for Inference-time Scaling in Text-to-visual Generation
Scaling visuals alone plateaus – revise prompts alongside visuals to unlock the best results.
S. Kim, S. Mo, M. N. Rizve, Y. Xu, D. Liu, J. Shin, T. Hinz, Conference on Computer Vision and Pattern Recognition 2026.
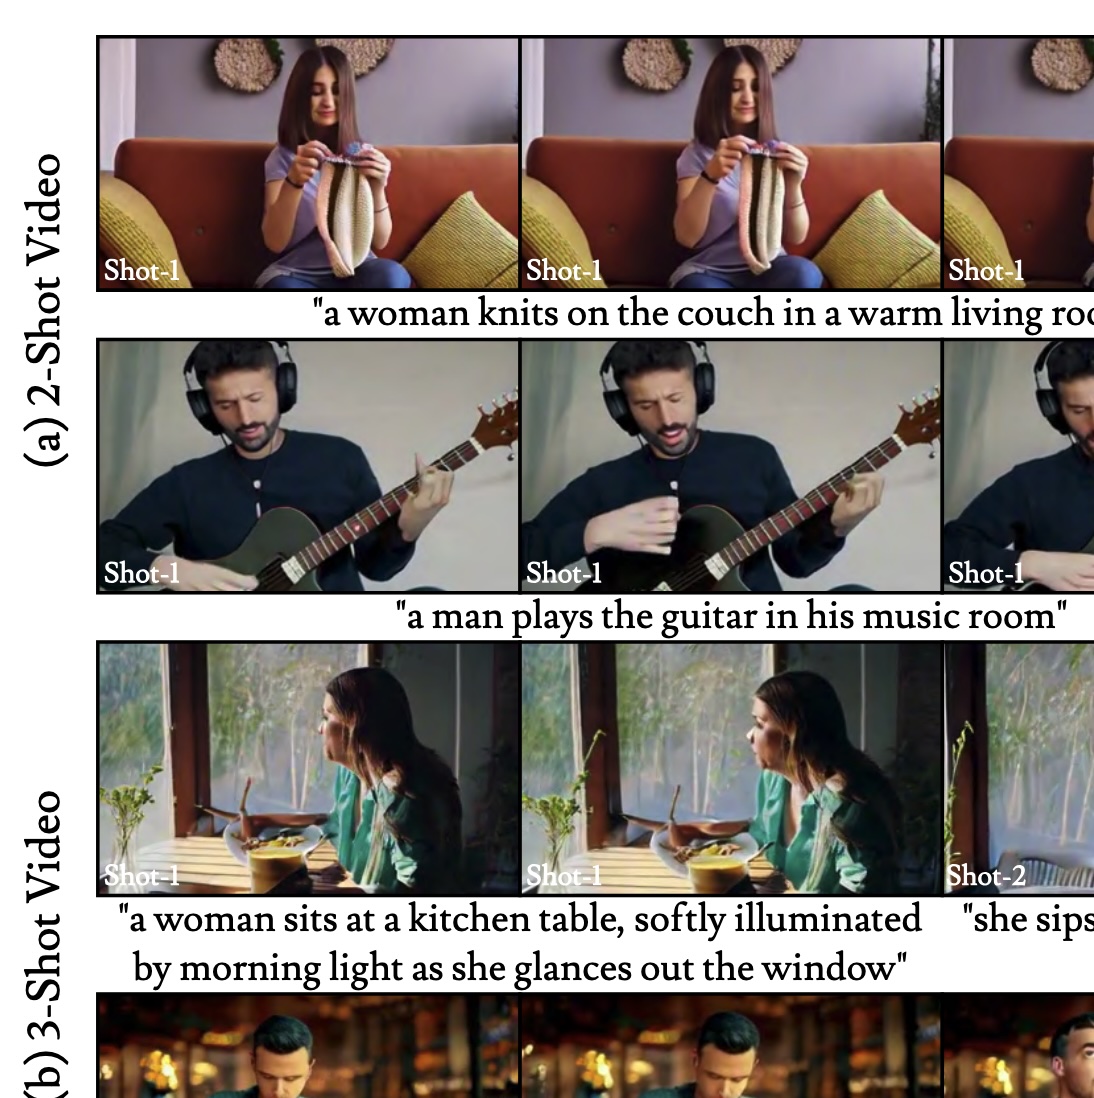
ShotAdapter: Text-to-Multi-Shot Video Generation with Diffusion Models
A framework that enables text-to-multi-shot video generation with shot-specific conditioning from a pretrained T2V model.
O. Kara, K. Singh, F. Liu, D. Ceylan, J. M. Rehg, T. Hinz, Conference on Computer Vision and Pattern Recognition 2025.

Personalized Residuals for Concept-Driven Text-to-Image Generation
A novel and efficient approach for enabling personalized image generation with diffusion models.
C. Ham, M. Fisher, J. Hays, N. Kolkin, Y. Liu, R. Zhang, T. Hinz, Conference on Computer Vision and Pattern Recognition 2024.
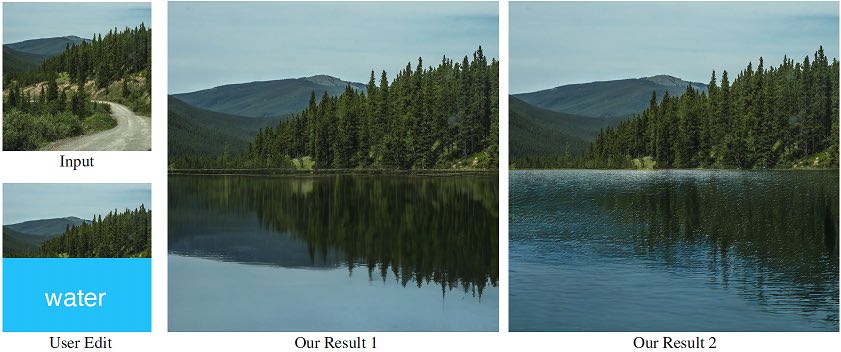
SmartBrush: Text and Shape Guided Object Inpainting with Diffusion Model
A diffusion model for shape-guided inpainting with better shape control and background preservation within the inpainted region.
S. Xie, Z. Zhang, Z. Lin, T. Hinz, K. Zhang, Conference on Computer Vision and Pattern Recognition 2023.
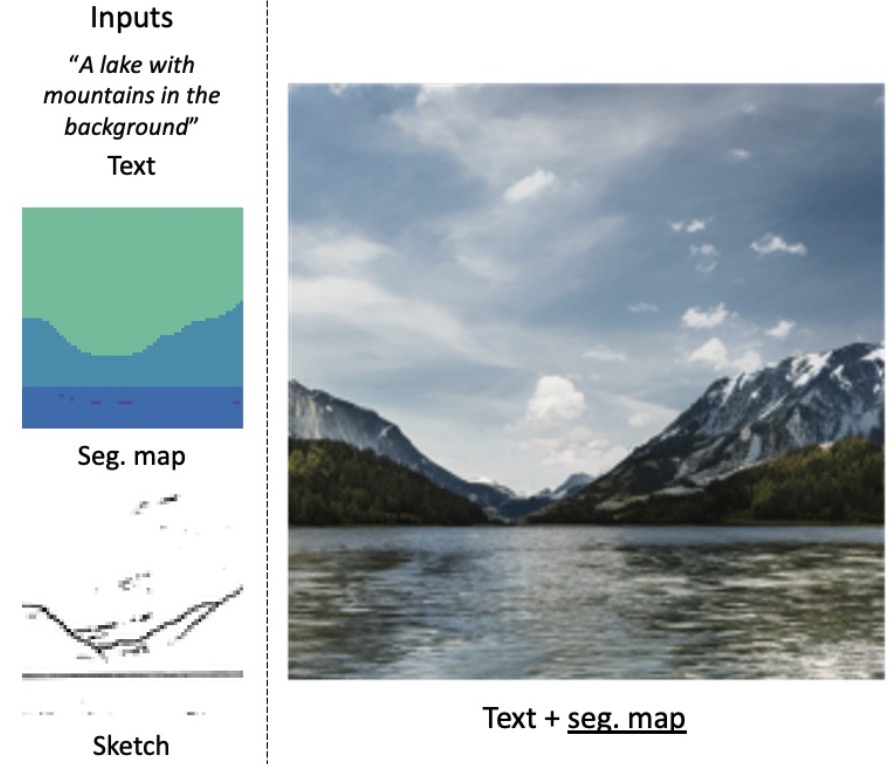
ASSET: Autoregressive Semantic Scene Editing with Transformers at High Resolutions
A neural architecture for automatically modifying an input high-resolution image according to a user's edits on its semantic segmentation map.
D. Liu, S. Shetty, T. Hinz, M. Fisher, R. Zhang, T. Park, E. Kalogerakis, ACM Transactions on Graphics (SIGGRAPH 2022) 2022.
Blog

My Remote Internship with Adobe Research (Summer 2020)
Posted on 18 Sep 2020 | Reading time: 4 minutes
I had the chance to do an internship with Adobe Research in San-Francisco. Due to COVID all Adobe staff are working from home and so I did my internship remotely from Germany.
Improved Techniques for Training Single-Image GANs
Posted on 24 Mar 2020 | Reading time: 7 minutes
Overview of our paper about training GANs on a single image for tasks such as image generation, image harmonization, and image animation.
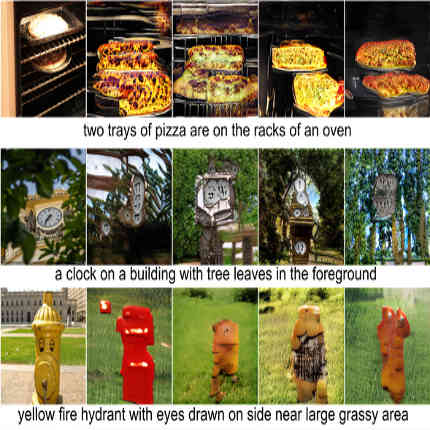
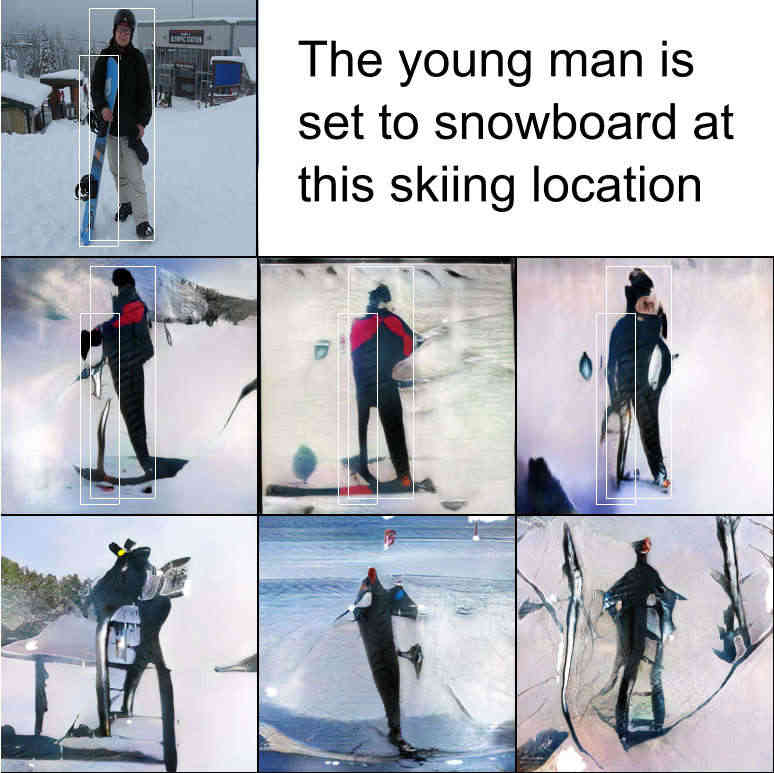
Semantic Object Accuracy for Generative Text-to-Image Synthesis
Posted on 30 Oct 2019 | Reading time: 9 minutes
Overview of our paper about our new model and evaluation metric for generative text-to-image synthesis models.
My Time At The Deep Learning And Reinforcement Learning Summer School (DLRLSS) in Edmonton (Canada)
Posted on 06 Aug 2019 | Reading time: 18 minutes
After attending the EEMLSS I was lucky enough to also attend the Deep Learning And Reinforcement Learning Summer School (DLRLSS) in Edmonton (Canada) 2019.
See All